Empes Infrastructure

Foundations your reporting can stand on

We build the data and technology foundation behind the scenes, so your reporting, automation and digital transformation efforts have something reliable to stand on.

What it is for

Dashboards, agents and automations are only as good as the data under them. When that layer is a collection of one-off pipelines, every new source is a project and nobody fully trusts the numbers.

What we build

  • Data engineering. Ingestion, modelling and transformation that is version-controlled and tested: dbt, SQL and Python on a warehouse such as Amazon Redshift.
  • Cloud engineering. Infrastructure as code (AWS CDK), containerised processing on Kubernetes, and orchestration with tools such as Argo Workflows.
  • System integration. Standard entry points (API, SFTP, JDBC), so sources such as CRM, ERP and research databases arrive the same way.
  • Digital transformation. The technical foundation a wider change depends on, built so it can be extended rather than replaced.

How we approach scale

Scale is not just about bigger servers; it is about better abstractions. We prefer one framework, configured per source, over many pipelines written by hand.

Proof

The enterprise data infrastructure case study: a metadata-driven ingestion framework for a global pharmaceutical company, managing 300+ sources and 70+ TB, that reduced source onboarding from weeks to days. The architecture is explained in the guide Data ingestion at scale.
Work

Global pharmaceutical · 2025

Scaling enterprise data infrastructure: a 300+ source ingestion framework

A global pharmaceutical company had more than 300 data sources and over 70 TB of data. We built one framework that brings every source in the same way, on AWS, so a new source takes days instead of weeks.

300+ data sources on one framework, 70+ TB

Read the case study

Mid-sized company · 2026

A private AI workspace for a company's staff: one chat, chosen models, costs that stay in bounds

Staff at a mid-sized company were using public AI assistants on their own accounts. We built the company its own AI workspace on Open WebUI and LiteLLM, on its own server: work login, models the company chose, budgets that hold, and help built in.

Read the case study

Operations / B2B services · 2025

Reducing reporting friction through automation and data restructuring

A mid-size operations team spent hours every week building reports by hand that were out of date on arrival. We simplified the process first, then automated it, and the reports now update themselves.

4-6 h of manual work removed every week

Read the case study

Own product engineering · 2026

An agent factory: AI agents take a GitHub issue to a pull request, with a person in charge

How we build our own product with AI agents that turn a person's task into a tested, reviewed change, safely and predictably, and how a team like yours could do the same.

Read the case study

Sports club, amateur league · 2026

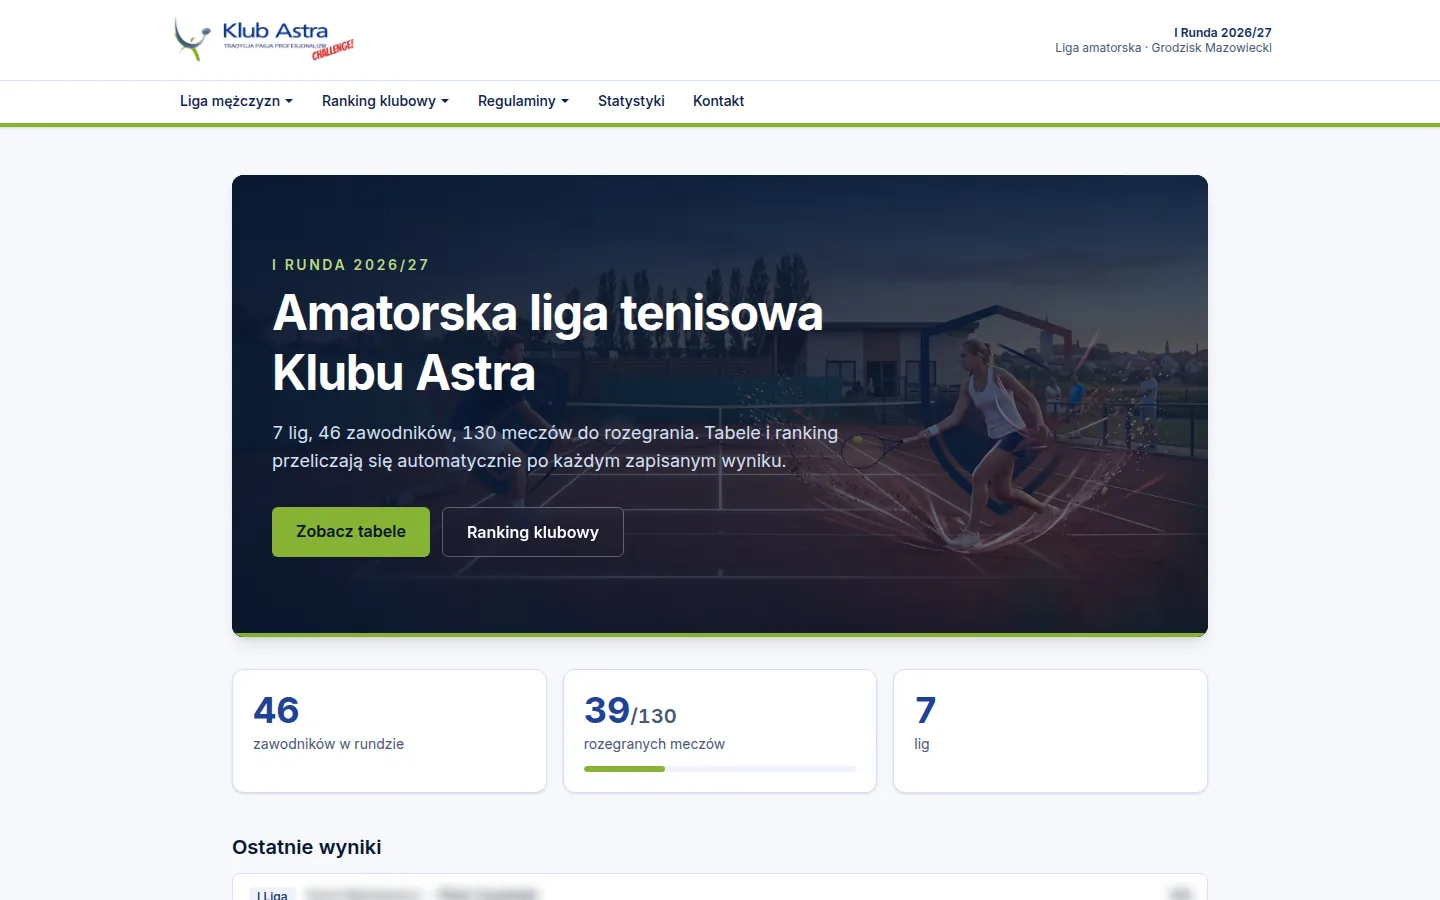
Liga Astra: a tennis league that publishes its own results

Klub Astra's amateur tennis league moved from WordPress, Google Sheets and embedded dashboards to a fast static site with a small admin panel, where every saved score updates the public tables and the club ranking.

about 2 min from a saved score to the public tables

Read the case study

Book a 30-min scoping call

Bring one process. We will tell you whether automation changes it, and what it would take.